The Hundred-Heads Test
A stranger says they called a hundred coin flips correctly. The arithmetic is airtight and it proves nothing. Work through the three visits — an unverifiable claim, a weighted coin, and rules agreed in advance — then run the same three failures on your own marketing data.
Advanced: reproducibility and the random seed
Every simulation on this page — the coin runs, the thousand-flip sequence, the dashboard campaigns and the twenty-four analyses — is generated in your browser from this one seed. Two people on the same seed see the identical page, which is what makes it safe to project in a lecture and have every student follow along on their own screen. You do not need to touch it.
Twenty-three years, twenty million dollars, no answer
The US government funded research into psychic spying from 1972 to 1995. Whether it worked turns out to be a question about method rather than about the paranormal — and the clearest way to see the method problem is with a coin.
- The record
- The stranger's claim
- The coin
- The rules
- The three failures
- A century of psychology
- Your own analysis
- Sources
What the record actually says
In 1972, two physicists at Stanford Research Institute began testing whether people could describe places they had never seen and could not perceive. The programme ran under a series of names, ending as Stargate, and by the 1990s it had absorbed roughly twenty million dollars of public money. Published results appeared in respectable venues. Some of the reported effects were statistically enormous.
In 1995 the CIA commissioned an outside review. Two reviewers examined the same body of work and disagreed about what it showed: the statistician concluded the effect was established, the psychologist concluded that the numbers, however anomalous, showed nothing of the kind. The programme was closed. Research continues today at private institutes, and the papers still report significant results.
What a remote viewing trial actually looked like
This is the Stanford Research Institute procedure, roughly as it ran from 1972. Work through one trial and you will have the whole argument in your hands.
- A pool of locations around the Bay Area is prepared in sealed envelopes. Nobody in the lab knows which is which.
- One envelope is drawn at random. An experimenter drives to that location and stands there for half an hour.
- Back in the lab the viewer — shielded, no contact of any kind — writes and sketches whatever impressions arrive.
- Afterwards a judge reads the transcript and decides which location in the pool it describes. Matching the right one counts as a hit.
There was an operational version too: a viewer given nothing but map coordinates, asked to describe a Soviet facility. Same structure, same judging step — except with no envelope to open afterwards, so no way to score it at all.
Six candidate locations, so pure guessing scores one in six — 16.7%.
There are three ways a study can hand you a genuinely impressive number and still tell you nothing. All three appear in this literature.
You have now run one trial. Which of the three do you think did the most damage to this programme?
A stranger claims a hundred heads
Someone knocks on your office door. They flipped a coin one hundred times, they say, and called every single one correctly. They know how unlikely that is. They did the arithmetic. They would like you to take it seriously.
What he says happened
One hundred coins, one hundred calls, every one correct. Here is his account of it.
Landed heads: 0 of 100
The arithmetic is not in dispute
Drag to set how many calls in a row they claim. This is the probability of that many correct calls by guessing alone: one half, multiplied by itself that many times.
That number is real, and it is astronomically small. Is it evidence?
So you ask for the record
Any one of these would let you check the claim yourself. Try all three.
The coin, at last — and a dull explanation
They come back a week later, and this time they are generous with their methods. Here is the coin. Here is the log. Sit and watch. They call heads on every flip, and they are not lying to you about any of it.
They will call heads a hundred times with their own coin. What do you expect to see?
Their coin, their flips, your eyes
His coin, on your desk, in your hands. Flip it and watch what it does.
The heavy side ends up underneath. Which means the light side — heads — ends up staring at you.
He calls heads before every single flip.
Below, filled circles are heads, so filled circles are the calls he got right.
heads — he called heads, so this one is correct tails — a miss
Now you have the coin, so bend it yourself. How honest does a coin have to be before a hundred correct calls stops being explainable?
And now watch his hundred coins again, with the benefit of having held one.
Landed heads: 0 of 100
These are his coins, tossed at the bias you set above. They barely even turn over.
The rules you agree on first
Nobody was fooling anybody. The coin was simply bad, and a bad coin produces a tiny p-value all on its own. So the two of you sit down — before any data exists — and agree on the terms under which you would be convinced.
- A coin neither of you owns, supplied and inspected by a third party
- The claimant never handles the coin
- Each call written down and witnessed before the flip leaves the hand
- The number of flips fixed now, in writing: one thousand
- The bar for “beyond guessing” fixed now: 55% or better across the full thousand
- Every flip reported, including the boring ones
The run
The story stipulates the opening: the first ten calls are all correct. Everything after that is an honest fair coin against an honest guesser. Watch the hit rate, and press space to flip one at a time.
This sequence is drawn from the seed at the top of the page. “Start over” deals the next run from that same seed, so the whole series replays identically for anyone opening the same link.
Five flips is where every extraordinary claim looks extraordinary.
The same three failures, now in the real research record
You have now met all three failures with a coin in your hand. Each one was a visit from the stranger, and in plain terms they were: one, an impressive number you were not allowed to check; two, a number you could check that turned out to have a dull cause; and three, a number produced under rules nobody had fixed before the data existed. Here they are again in the programme you started with, in the order the field ran into them.
| The failure | What you were given | Why the number could not settle it |
|---|---|---|
| One — nothing you could check | An impressive number, data nobody outside could inspect | Early results rested on transcripts and operational hits described by the researchers themselves. Reviewers outside the programme could not audit what they were being asked to accept. |
| Two — a real effect with a dull cause | Data you can check, and something else causing the result | When outside researchers finally examined the transcripts, they found cues inside them — enough to let a judge match a description to a target without any clairvoyance. The p-values were correct. The coin was weighted. |
| Three — no rules fixed in advance | Terms fixed before the data | Reached only recently. Once the design was locked in advance and agreed to by both sides, the effect went to chance and stayed there. |
Where to read the record yourself
- The programme review. Mumford, M. D., Rose, A. M., & Goslin, D. A. (1995). An Evaluation of Remote Viewing: Research and Applications. American Institutes for Research. The split verdict is the interesting part: Jessica Utts concluded the effect was established, Ray Hyman concluded it was not — see Hyman, R. (1996), Journal of Scientific Exploration, 10(1), 31–58. Cite this honestly or you will be ambushed by someone who has read both halves.
- The leak. Marks, D., & Kammann, R. (1978). Information transmission in remote viewing experiments. Nature, 274, 680–681. Their duplicate experiments failed to reproduce the effect, and they located cues in the original transcripts. Follow-up: Marks (1981), Nature, 292, 177.
- The third visit. Kekecs, Z., et al. (2023). Royal Society Open Science, 10, 191375. A large collaboration that fixed its protocol in advance through a consensus process including both believers and sceptics, preregistered it, had it independently audited, and deposited the data as it was collected. Result: chance. Extended in Walleczek, J., et al. (2025), PLOS ONE, 20(11), e0335330: 26,483 participants, 420,472 trials, and a failure to replicate.
- The stopping-rule problem, measured across a whole field. Bösch, H., Steinkamp, F., & Boller, E. (2006). Psychological Bulletin, 132, 497–523. Reported effect size falls as sample size rises — the fingerprint of results being reported when they look good.
It was never only the psychics
The same three failures run straight through the respectable middle of psychology, and they were not mostly the work of frauds. They were the work of careful people using the standard methods of their day, published in the best journals, taught to students, and believed for decades.
Four distinct things go wrong in the cases below. Only one of them is dishonesty, and it is the least of the four.
1907Clever Hans, the counting horsethe setup did it
A horse in Berlin appeared to do arithmetic, tapping out answers with a hoof. Oskar Pfungst tested it properly and found the horse was superb — at reading the involuntary posture and breathing changes of whoever knew the answer. Ask a question nobody in the room could answer and Hans was useless.
Your coin was weighted. The effect was real, the observations were honest, and the cause was the setup rather than the horse. Every blinding procedure in modern research descends from this horse.
1920Little Alberttoo small to tell
Watson and Rayner conditioned one infant to fear a white rat, and the result was generalised into a theory of human emotional development that ran in textbooks for fifty years. One participant. No control condition. No follow-up.
Five flips, all heads. A finding this thin cannot fail — there is no result it could have produced that anyone would have reported as a null.
1962Cohen counts the power, and nobody movestoo small to tell
Jacob Cohen worked through a year of the Journal of Abnormal and Social Psychology and calculated what chance those studies had of detecting a real effect of medium size. The answer was 48% — a coin flip. For small effects, 18%.
Sedlmeier and Gigerenzer checked again in 1989, after twenty-seven years of the field being able to read Cohen's paper. Nothing had improved.
This is the quiet one. A literature of underpowered studies that only publishes the wins will be full of significant results and almost none of them will replicate. The arithmetic for this was published in 1962 and it changed nothing for half a century.
1963The maze-bright ratsthe setup did it
Rosenthal and Fode handed student experimenters rats at random, telling some the animals were bred to be clever and others that theirs were dull. The rats performed exactly as the students had been led to expect.
The weighted coin was inside the researcher. Nobody cheated. What they expected leaked into how they handled the animals, how they timed them, and what they wrote down. This is why the person running the session is now kept blind to condition — and why “it does not work when a sceptic watches” is such a revealing excuse.
1971The Stanford prison studythe setup did it
The most famous demonstration in social psychology, taught as evidence that ordinary people become brutal when handed a uniform. Archival work published by Le Texier in American Psychologist (2019) documents guards being coached toward the behaviour, and the lead researcher running the prison rather than observing it.
No third party, no rules set in advance, no result that could have counted as a null. A study designed this way returns what its designer expects, and it is not obvious from the outside that anything went wrong.
1976Cyril Burt's twinsinvented data
Decades of twin correlations on inherited intelligence, some of them suspiciously stable across samples, from co-authors nobody could later locate. The case is still argued over, and at minimum the data cannot be verified.
Here is the fraud case, and notice how little it teaches you. Nothing in your methods training protects against a colleague inventing numbers. What protects you is that other people can check.
2011Diederik Stapelinvented data
A prominent social psychologist, dozens of papers, more than fifty of them eventually retracted, built on data he had made up at his kitchen table. His graduate students never saw a raw dataset.
Detected by junior colleagues, not by peer review. The reviewers had no access to the data, which is the first visit all over again: an impressive number and nothing inspectable behind it.
2011Bem publishes precognition — and the field notices the problem is its ownflexible analysis
Daryl Bem reported nine experiments showing people could anticipate random future events, in the Journal of Personality and Social Psychology, one of the most selective journals in the discipline. It passed peer review because it used the field's completely ordinary methods.
That was the hinge. If the standard toolkit can produce publishable evidence for precognition, the problem is not Bem, and it is not psychic research. It is the toolkit — and everything else built with it is now in question. Psi research had accidentally become a stress test for psychology's methods, and the methods failed it.
2011False-positive psychologyflexible analysis
Simmons, Nelson and Simonsohn showed that a researcher making ordinary, defensible choices — which outcome to analyse, whether to exclude odd responses, whether to adjust for age or gender, whether to collect a few more participants — can push the false-positive rate far above 5% without doing anything they would recognise as cheating.
John, Loewenstein and Prelec surveyed psychologists a year later and found these practices were common and largely thought unremarkable.
You will try this yourself in the next panel.
2015The Reproducibility Projectflexible analysis
Around 270 researchers replicated 100 studies from three leading psychology journals, using original materials and larger samples. 97% of the original studies had reported a significant result. 36% of the replications did. Average effect sizes came in at half the original size.
Take the counter-argument seriously too: Gilbert and colleagues argued in Science that the replications were themselves flawed and the true reproducibility rate is far higher. The dispute is live, and a field that can argue in public about its own data is a field that is working.
2015 →The repair, which is just your third visitthe repair
Filing your plan in public before you collect anything: what you expect, how many people you will collect, who you will leave out, and exactly how you will crunch it. Journals reviewing and accepting a study based on its design, before anyone knows how it turned out, so a boring result cannot be punished. Journals asking, before you collect anything, whether your study is even big enough to detect what you are looking for. Open data and code. Multi-lab replications. People who disagree running the study together, both signing off on the plan before it starts.
Every item on that list is a term from the agreement you wrote with the coin flipper. None of it is new statistics. It is all just deciding what would count as convincing before you know what happened.
The one you are most likely to commit
Nobody in this room is going to invent data. The realistic risk is the third failure: making a series of small, reasonable analytic choices, and stopping when the result looks good. Below is a dataset where the two groups are identical by construction — the true difference is exactly zero. Everything is noise. Go find a significant result.
Twenty-four reasonable ways to look at nothing
160 customers, 80 shown creative A and 80 shown creative B, split properly at random this time. Afterwards each one rated ad recall and brand attitude, both on a 0–100 scale. You also know their age, their gender, and who rushed through the survey.
What you are doing here. You are the analyst, and your first look came back boring. Each control below is one ordinary choice you could defend to your director without blinking — which outcome to report, whether to drop inattentive respondents, whether to control for age, which customers to include. Keep changing them and watch the chance of this if no real difference figure. Your goal is to push it under 0.05. When you manage it, remember what is in this data: nothing. The two creatives are identical by construction.
The question you are asking right now: —
The true difference between these creatives is zero. Keep clicking.
Written the way a stats package would put it: —
Reading for this part
- Pfungst, O. (1911). Clever Hans (The Horse of Mr. von Osten). Rosenthal, R., & Fode, K. (1963). Behavioral Science, 8, 183–189.
- Cohen, J. (1962). The statistical power of abnormal-social psychological research. Journal of Abnormal and Social Psychology, 65, 145–153. Follow-up: Sedlmeier, P., & Gigerenzer, G. (1989), Psychological Bulletin, 105, 309–316.
- Le Texier, T. (2019). Debunking the Stanford Prison Experiment. American Psychologist, 74, 823–839.
- Bem, D. J. (2011). Journal of Personality and Social Psychology, 100, 407–425. Read alongside Wagenmakers, E.-J., et al. (2011), same issue, 426–432.
- Simmons, J., Nelson, L., & Simonsohn, U. (2011). False-positive psychology. Psychological Science, 22, 1359–1366. John, L., Loewenstein, G., & Prelec, D. (2012), Psychological Science, 23, 524–532.
- Open Science Collaboration (2015). Estimating the reproducibility of psychological science. Science, 349, aac4716. Dissent: Gilbert, D., et al. (2016), Science, 351, 1037.
- Ioannidis, J. P. A. (2005). Why most published research findings are false. PLoS Medicine, 2, e124.
Your own analysis
Here is your job. You are the marketing analyst at Halden Supply, a direct-to-consumer outdoor gear company: eleven million in annual revenue, a four-person marketing team, and a media budget of about ninety thousand a month. Three things land on your desk this quarter. Each one is a visit.
Monday, 10 a.m. — the vendor meeting
A rep from Northstar Retargeting is in your conference room with a deck. Slide four says: “+34% incremental conversion lift for a national athletic footwear retailer.” Their annual contract is $48,000. Your director likes them and wants your read by Thursday.
You have one meeting to find out whether that 34% means anything. Ask.
Six questions and the answers you get
Click each one. These are the actual responses — nobody in the room is lying to you.
Wednesday — the landing page test that worked
Your own test, run in-house. Two versions of the product landing page, 4,000 visitors each, two weeks. Version B moved conversion from 3.52% to 4.62% — a 31% relative lift, p = 0.013. You are about to recommend rolling B out to the whole site, which means a developer sprint and roughly $6,000 of work.
Before you send that email, check the one thing nobody checks.
The Halden Supply landing page test
Here is what you would put in the deck. It is all correct.
| Page version | Conversions out of visitors | Conversion rate |
|---|---|---|
| Version A (control) | 141 conversions / 4,000 visitors | 3.52% |
| Version B (new hero image) | 185 conversions / 4,000 visitors | 4.62% |
| Difference | +1.10 percentage points, +31% relative | p = 0.013 |
Friday — the creative test, with the media buyer waiting
Two ad creatives running in paid social, $1,400 a day. Nobody wrote down how long the test would run. Your media buyer needs to shift budget to the winner before the weekend, and she messages you every morning at nine to ask whether you can call it yet.
Below is that test. The two creatives are identical in their true performance — the difference between them is exactly zero, by construction. Advance it day by day and stop when you would actually stop in real life, with her waiting.
Halden Supply creative test — live
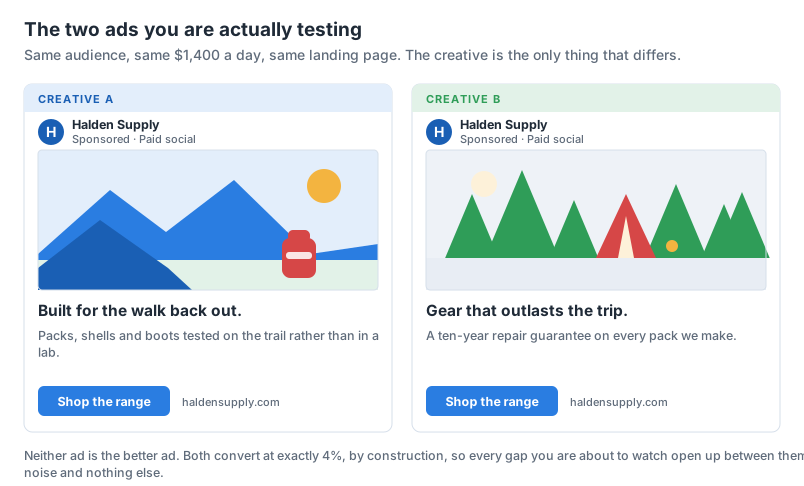
Creative A and Creative B, both converting at exactly 4%, 400 visitors each per day. The gold line is the observed lift; the green band is the range that counts as a tie. Any day the line escapes the band is a day you could tell her B is the winner and be believed.
Day 0. She has not messaged yet. Advance one day at a time.
What you write down before any of this starts
- “We will run the landing page test to 8,000 visitors, two weeks, whichever comes second” — written down before launch, so there is no day 9 decision to make
- “The metric is conversion rate, not add-to-cart, not time on page” — one primary metric, named in advance
- “B wins if it beats A by more than 0.8 percentage points” — the margin fixed while you still have no idea which way it will go
- “Before reading the result, we check arm composition on new-versus-returning, device, and traffic source” — a step you do every time, before you let yourself believe the result
- “If we cut the result by visitor type or segment, we say so in the email and we say how many cuts we tried”
- “We circulate the result whichever way it comes out” — including the four tests last quarter that found nothing
The cost is real: you will kill findings you liked, and some of them were probably true. Version B might genuinely be better. You will not get to claim it on this data. What you buy is that when you walk into your director's office and say a number, it means something — because the process that produced it was free to come back empty, and did not.
The question was never whether the number is impressive. It is whether the design was capable of producing an unimpressive one.
Everything on this page, and where to check it
How to use this list. Every figure, date and claim on this page traces to one of these. Details were checked against publisher records rather than recalled — if you find a discrepancy, the publisher is right and this page is wrong.
Where a paper was publicly rebutted, the rebuttal is listed underneath it. That is deliberate. A page arguing that you should be able to check things is in no position to quietly omit the other side's reply.
A. The remote viewing programme
The original claim, the critiques, and the government review that closed it.
- 1Targ, R., & Puthoff, H. (1974). Information transmission under conditions of sensory shielding. Nature, 251(5476), 602–607. doi:10.1038/251602a0 — the paper that put remote viewing into a top journal, and the protocol staged in part one.
- 2Marks, D., & Kammann, R. (1978). Information transmission in remote viewing experiments. Nature, 274, 680–681. doi:10.1038/274680a0 — failed duplication, and the discovery of cues in the original transcripts.
- 3Marks, D. (1981). Sensory cues invalidate remote viewing experiments. Nature, 292, 177. doi:10.1038/292177a0Reply: Puthoff, H., & Targ, R. (1981). Rebuttal of criticisms of remote viewing experiments. Nature, 292, 388. doi:10.1038/292388a0
- 4Marks, D., & Scott, C. (1986). Remote viewing exposed. Nature, 319, 444. doi:10.1038/319444a0
- 5Mumford, M. D., Rose, A. M., & Goslin, D. A. (1995). An Evaluation of Remote Viewing: Research and Applications. American Institutes for Research, 29 September 1995. The CIA-commissioned review that ended the programme. Declassified copy in the CIA reading room.
- 6Utts, J. M. (1996). An assessment of the evidence for psychic functioning. Journal of Scientific Exploration, 10(1), 3–30. The AIR panel's statistician, concluding the effect was established. Read this one if you only read one.And the other half of the same panel: Hyman, R. (1996). Evaluation of program on anomalous mental phenomena. Journal of Scientific Exploration, 10(1), 31–58. Followed by Utts, J. M. (1996), Response to Ray Hyman's report, same issue, 59–61. Both also appeared in Journal of Parapsychology, 59(4).
B. Psi as a stress test for ordinary methods
How a precognition paper in a leading journal turned into an argument about everybody's statistics.
- 7Bem, D. J. (2011). Feeling the future: Experimental evidence for anomalous retroactive influences on cognition and affect. Journal of Personality and Social Psychology, 100(3), 407–425. doi:10.1037/a0021524Critique: Wagenmakers, E.-J., Wetzels, R., Borsboom, D., & van der Maas, H. L. J. (2011). Why psychologists must change the way they analyze their data: The case of psi. JPSP, 100(3), 426–432. doi:10.1037/a0022790 Bem's answer: Bem, D. J., Utts, J., & Johnson, W. O. (2011). Must psychologists change the way they analyze their data? JPSP, 101, 716–719.
- 8Bem, D., Tressoldi, P., Rabeyron, T., & Duggan, M. (2016). Feeling the future: A meta-analysis of 90 experiments on the anomalous anticipation of random future events. F1000Research, 4, 1188. The proponents' strongest aggregate case. Included so students can see what the argument looks like from the other side.
- 9Kekecs, Z., et al. (2023). Raising the value of research studies in psychological science by increasing the credibility of research reports: The Transparent Psi Project. Royal Society Open Science, 10(2), 191375. doi:10.1098/rsos.191375 — protocol fixed in advance by consensus, independently audited, born-open data. Null result.And its own correction, which is the most interesting thing in this whole list: Kekecs, Z., et al. (2023). Correction. Royal Society Open Science, 10(8), 231080. doi:10.1098/rsos.231080 — an independent audit by J. E. Kennedy found unlisted protocol deviations, and the authors published the corrections. The audit judged them unlikely to have changed the null conclusion, while noting they would have mattered more had the result been positive.
- 10Walleczek, J., von Stillfried, N., Schmidt, S., Wittmann, M., Kirmse, K. A., Moll, J., & Kekecs, Z. (2025). Metascientific replication project with the advanced meta-experimental protocol of the transparent psi project procedures for testing the precognitive effect claimed by Bem. PLOS ONE, 20(11), e0335330. doi:10.1371/journal.pone.0335330 — 26,483 participants, 420,472 critical trials. Study 1 failed to replicate.
- 11Bösch, H., Steinkamp, F., & Boller, E. (2006). Examining psychokinesis: The interaction of human intention with random number generators — a meta-analysis. Psychological Bulletin, 132(4), 497–523. doi:10.1037/0033-2909.132.4.497 — 380 studies; a small significant effect, with effect size inversely related to sample size.Both sides replied in the same issue: Radin, D., Nelson, R., Dobyns, Y., & Houtkooper, J. (2006), 132(4), 529–532; Wilson, D. B., & Shadish, W. R. (2006), 132(4), 524–528.
C. Psychology's own record
The cases in part four, in the order they appear.
- 12Pfungst, O. (1911). Clever Hans (The Horse of Mr. von Osten): A Contribution to Experimental Animal and Human Psychology (C. L. Rahn, Trans.). Henry Holt.
- 13Cohen, J. (1962). The statistical power of abnormal-social psychological research: A review. Journal of Abnormal and Social Psychology, 65(3), 145–153. Mean power to detect a medium effect: 48%.Checked again 27 years later: Sedlmeier, P., & Gigerenzer, G. (1989). Do studies of statistical power have an effect on the power of studies? Psychological Bulletin, 105(2), 309–316. doi:10.1037/0033-2909.105.2.309
- 14Rosenthal, R., & Fode, K. L. (1963). The effect of experimenter bias on the performance of the albino rat. Behavioral Science, 8(3), 183–189. doi:10.1002/bs.3830080302
- 15Le Texier, T. (2019). Debunking the Stanford Prison Experiment. American Psychologist, 74(7), 823–839. doi:10.1037/amp0000401 — archival work and interviews with 15 participants. Zimbardo and colleagues published replies in the same journal; the dispute is ongoing.
- 16Mackintosh, N. J. (Ed.). (1995). Cyril Burt: Fraud or Framed? Oxford University Press. doi:10.1093/acprof:oso/9780198523369.001.0001 — contributors conclude that both the prosecution and the defence cases are seriously flawed, which is why this page treats the Burt affair as unresolved.
- 17Levelt, W. J. M., Drenth, P., & Noort, E. (Eds.). (2012). Flawed Science: The Fraudulent Research Practices of Social Psychologist Diederik Stapel. Commissioned by Tilburg University, the University of Amsterdam and the University of Groningen. Fraud established in 55 publications and in material used in 10 dissertations; co-authors and doctoral students were found to be victims rather than participants.
D. Flexible analysis, and the audit of a whole field
The papers behind the 24-analyses panel and the dashboard game.
- 18Simmons, J. P., Nelson, L. D., & Simonsohn, U. (2011). False-positive psychology: Undisclosed flexibility in data collection and analysis allows presenting anything as significant. Psychological Science, 22(11), 1359–1366. doi:10.1177/0956797611417632 — the direct ancestor of the 24-analyses panel in part four.
- 19John, L. K., Loewenstein, G., & Prelec, D. (2012). Measuring the prevalence of questionable research practices with incentives for truth telling. Psychological Science, 23(5), 524–532. doi:10.1177/0956797611430953
- 20Open Science Collaboration. (2015). Estimating the reproducibility of psychological science. Science, 349(6251), aac4716. doi:10.1126/science.aac4716 — 100 replications. 97% of originals significant, 36% of replications significant; mean effect size fell from r = .403 to r = .197.Dissent: Gilbert, D. T., King, G., Pettigrew, S., & Wilson, T. D. (2016). Comment on “Estimating the reproducibility of psychological science.” Science, 351(6277), 1037. doi:10.1126/science.aad7243 — argues the project contains statistical errors and that corrected reproducibility is far higher. The Open Science Collaboration published a response in the same issue.
- 21Ioannidis, J. P. A. (2005). Why most published research findings are false. PLoS Medicine, 2(8), e124. doi:10.1371/journal.pmed.0020124
E. What is not a source
Said plainly, so nobody cites the wrong thing back at you.
- —Halden Supply does not exist. The vendor meeting, the landing page test and the creative test in part five are written scenarios. Their numbers are internally consistent and were checked arithmetically — the confounded test really does give +31% at p = 0.013 overall and nothing inside either visitor group — but no company, campaign or client is being described.
- —The six Bay Area locations in part one are invented, chosen to resemble the kind of target pool the SRI programme used. The transcript is written for this page, not quoted from a real trial.
- —Every simulation here generates its own data at runtime. The coin runs, the dashboard campaigns and the 24 analyses are random draws in your browser, built with no real effect in them. The percentages the page reports are computed live from those draws, not copied from the papers above.